Hightouch lets you pull data stored in Azure Synapse and push it to downstream destinations. Connecting Hightouch to Azure Synapse requires some setup in both platforms. In Azure Synapse, you need to configure your firewall settings.
By default, Azure protects your Synapse data from any external IP address from connecting to your Synapse workspace. Follow these steps to add Hightouch’s IP addresses to the firewall.
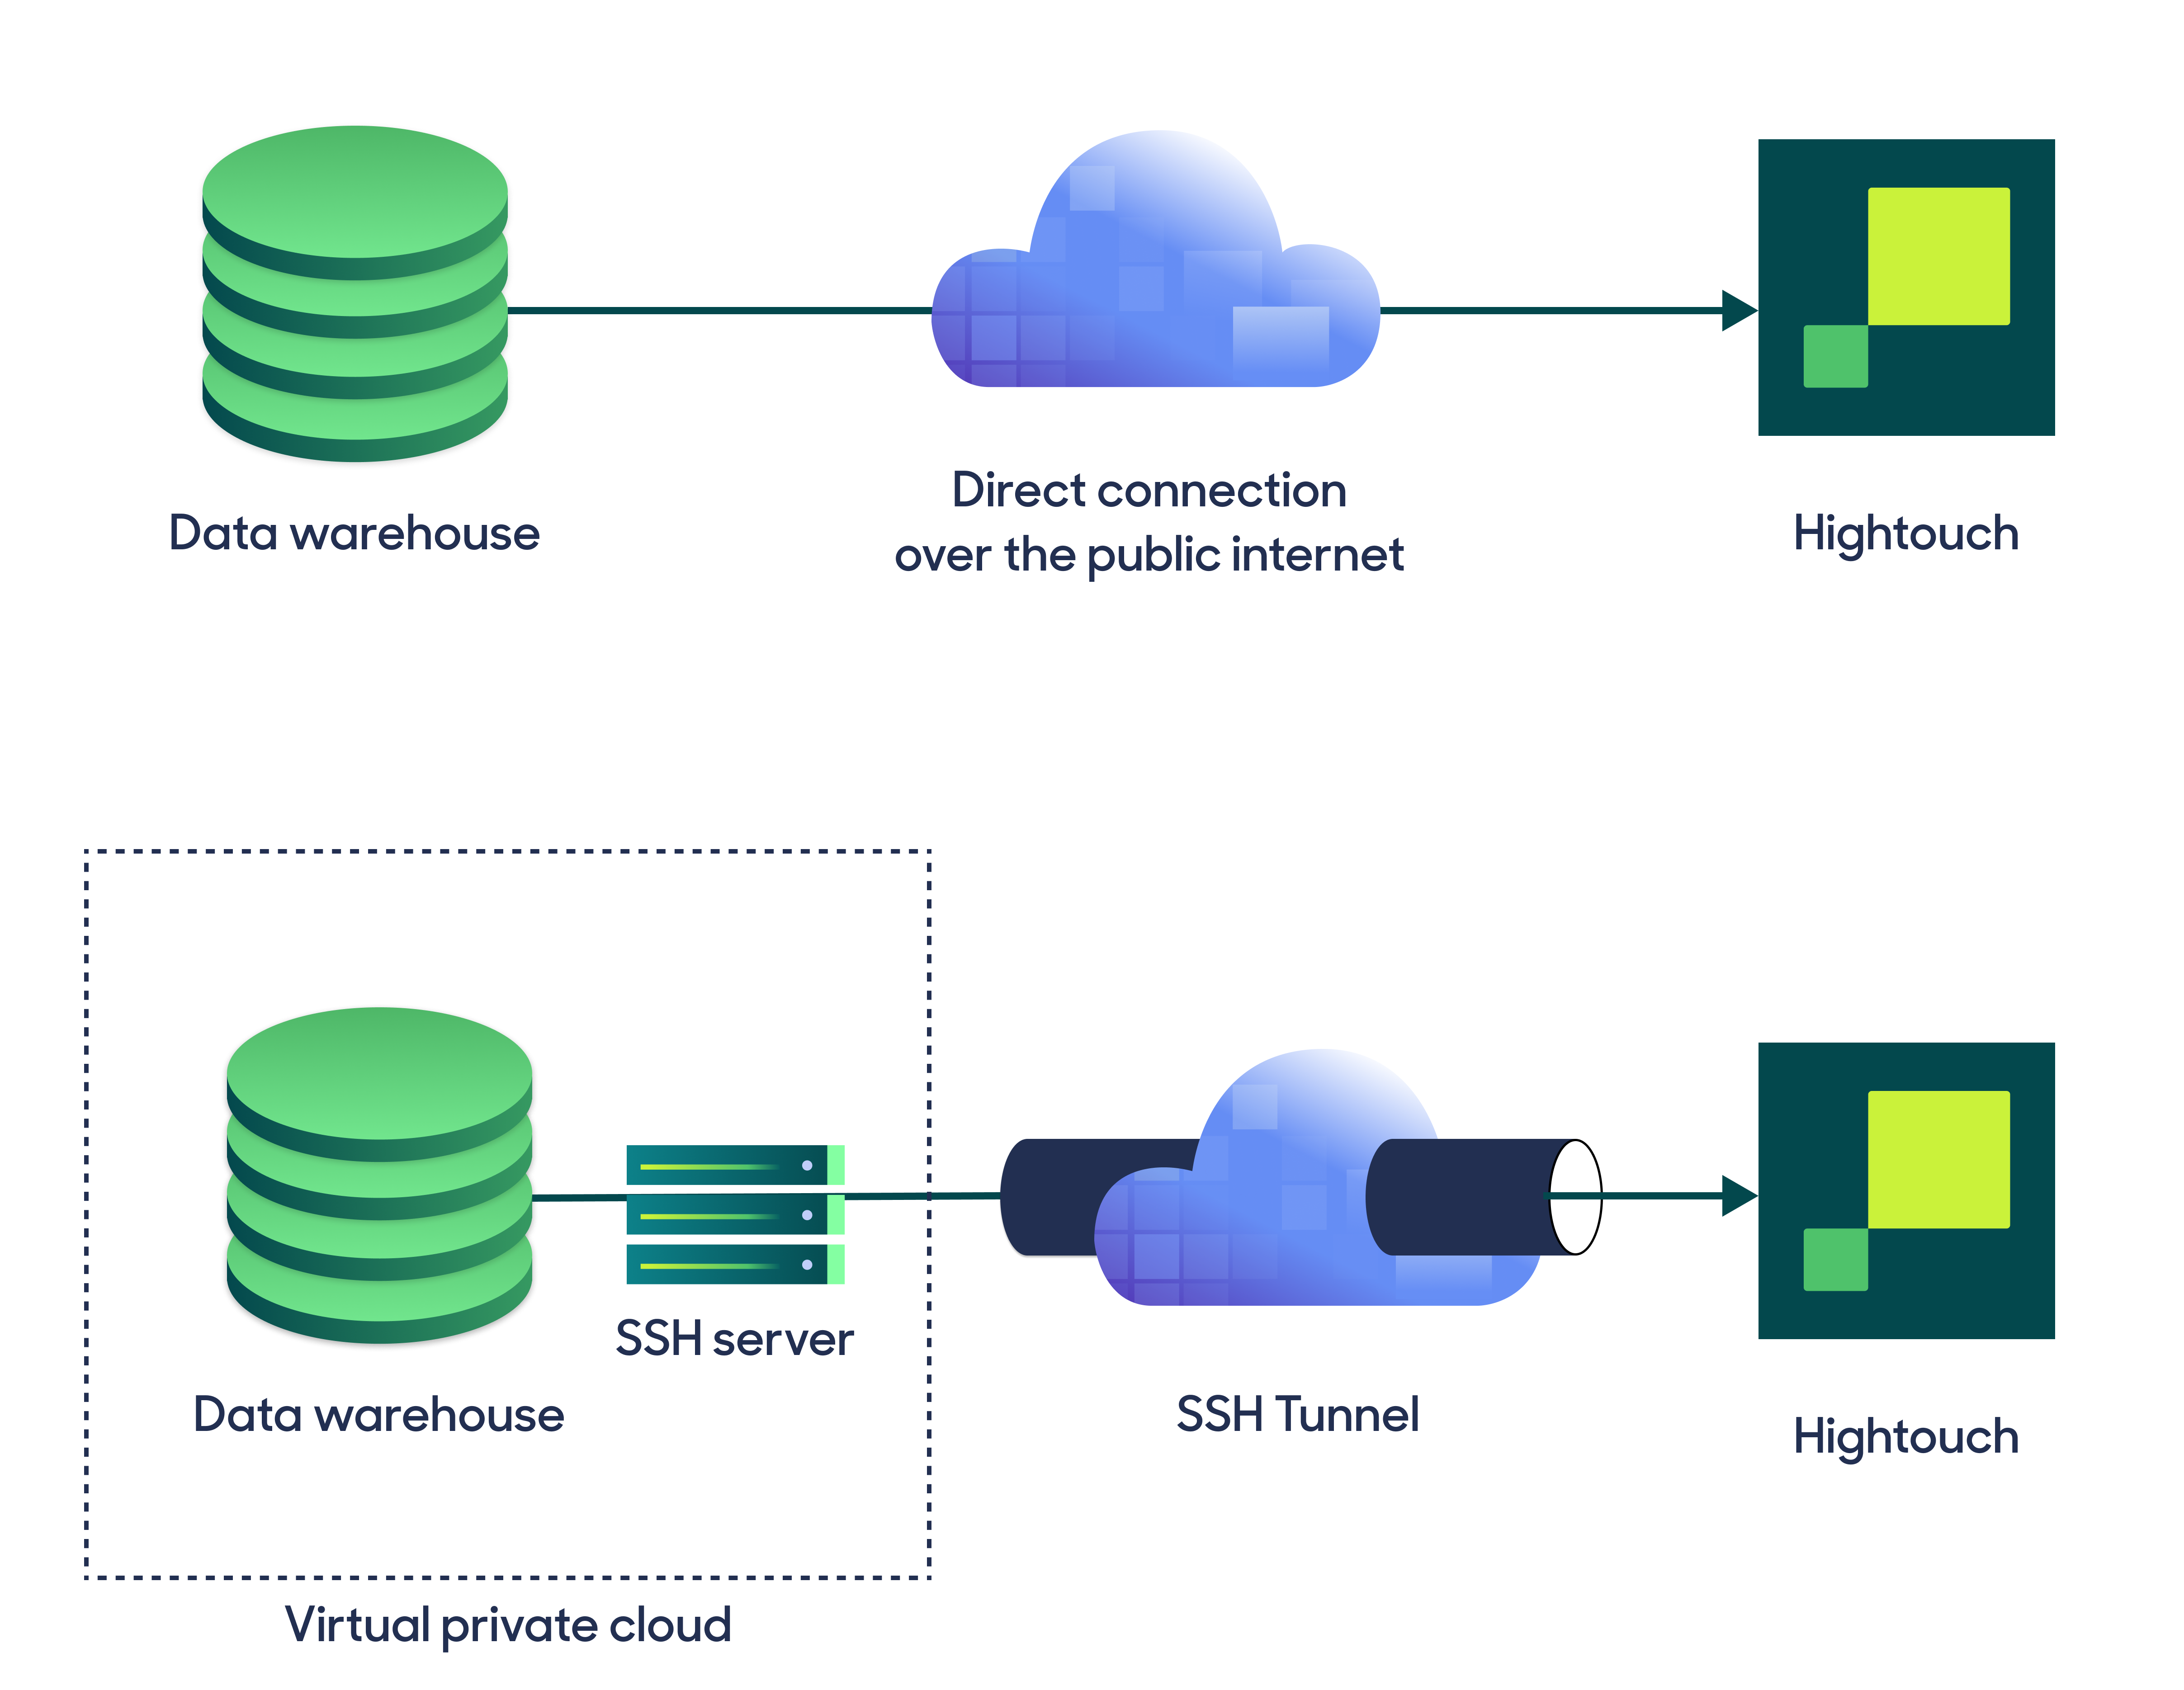
Hightouch can connect directly to true over the public internet or via an SSH tunnel. Since data is encrypted in transit via TLS, a direct connection is suitable for most use cases. You may need to set up a tunnel if your true instance is on a private network or virtual private cloud (VPC).Hightouch supports both standard and reverse SSH tunnels. To learn more about SSH tunneling, refer to Hightouch’s tunneling documentation.
Name your client secret and select its expiration date. To maintain access to Azure Synapse, make sure to refresh your client secret prior to its expiration.
Note your client secret Value now as it cannot be retrieved later. It will be used to connect Hightouch to Azure Synapse.
Finally, you can enter the following fields into Hightouch that were created during the above instructions:
Tenant ID (or Directory ID)
Client ID (or Application ID)
If you chose to create a Client Secret for your service principal, you’ll enter it here.If you instead chose to create a Certificate, enter in your certificate’s Thumbprint and the associated private key. Make sure that the private key is in PEM format and includes the header and footer.
If connecting via Connection String, simply enter your connection string in this format: Server=server;Database=database;User Id=username;Password=password;Encrypt=boolean.
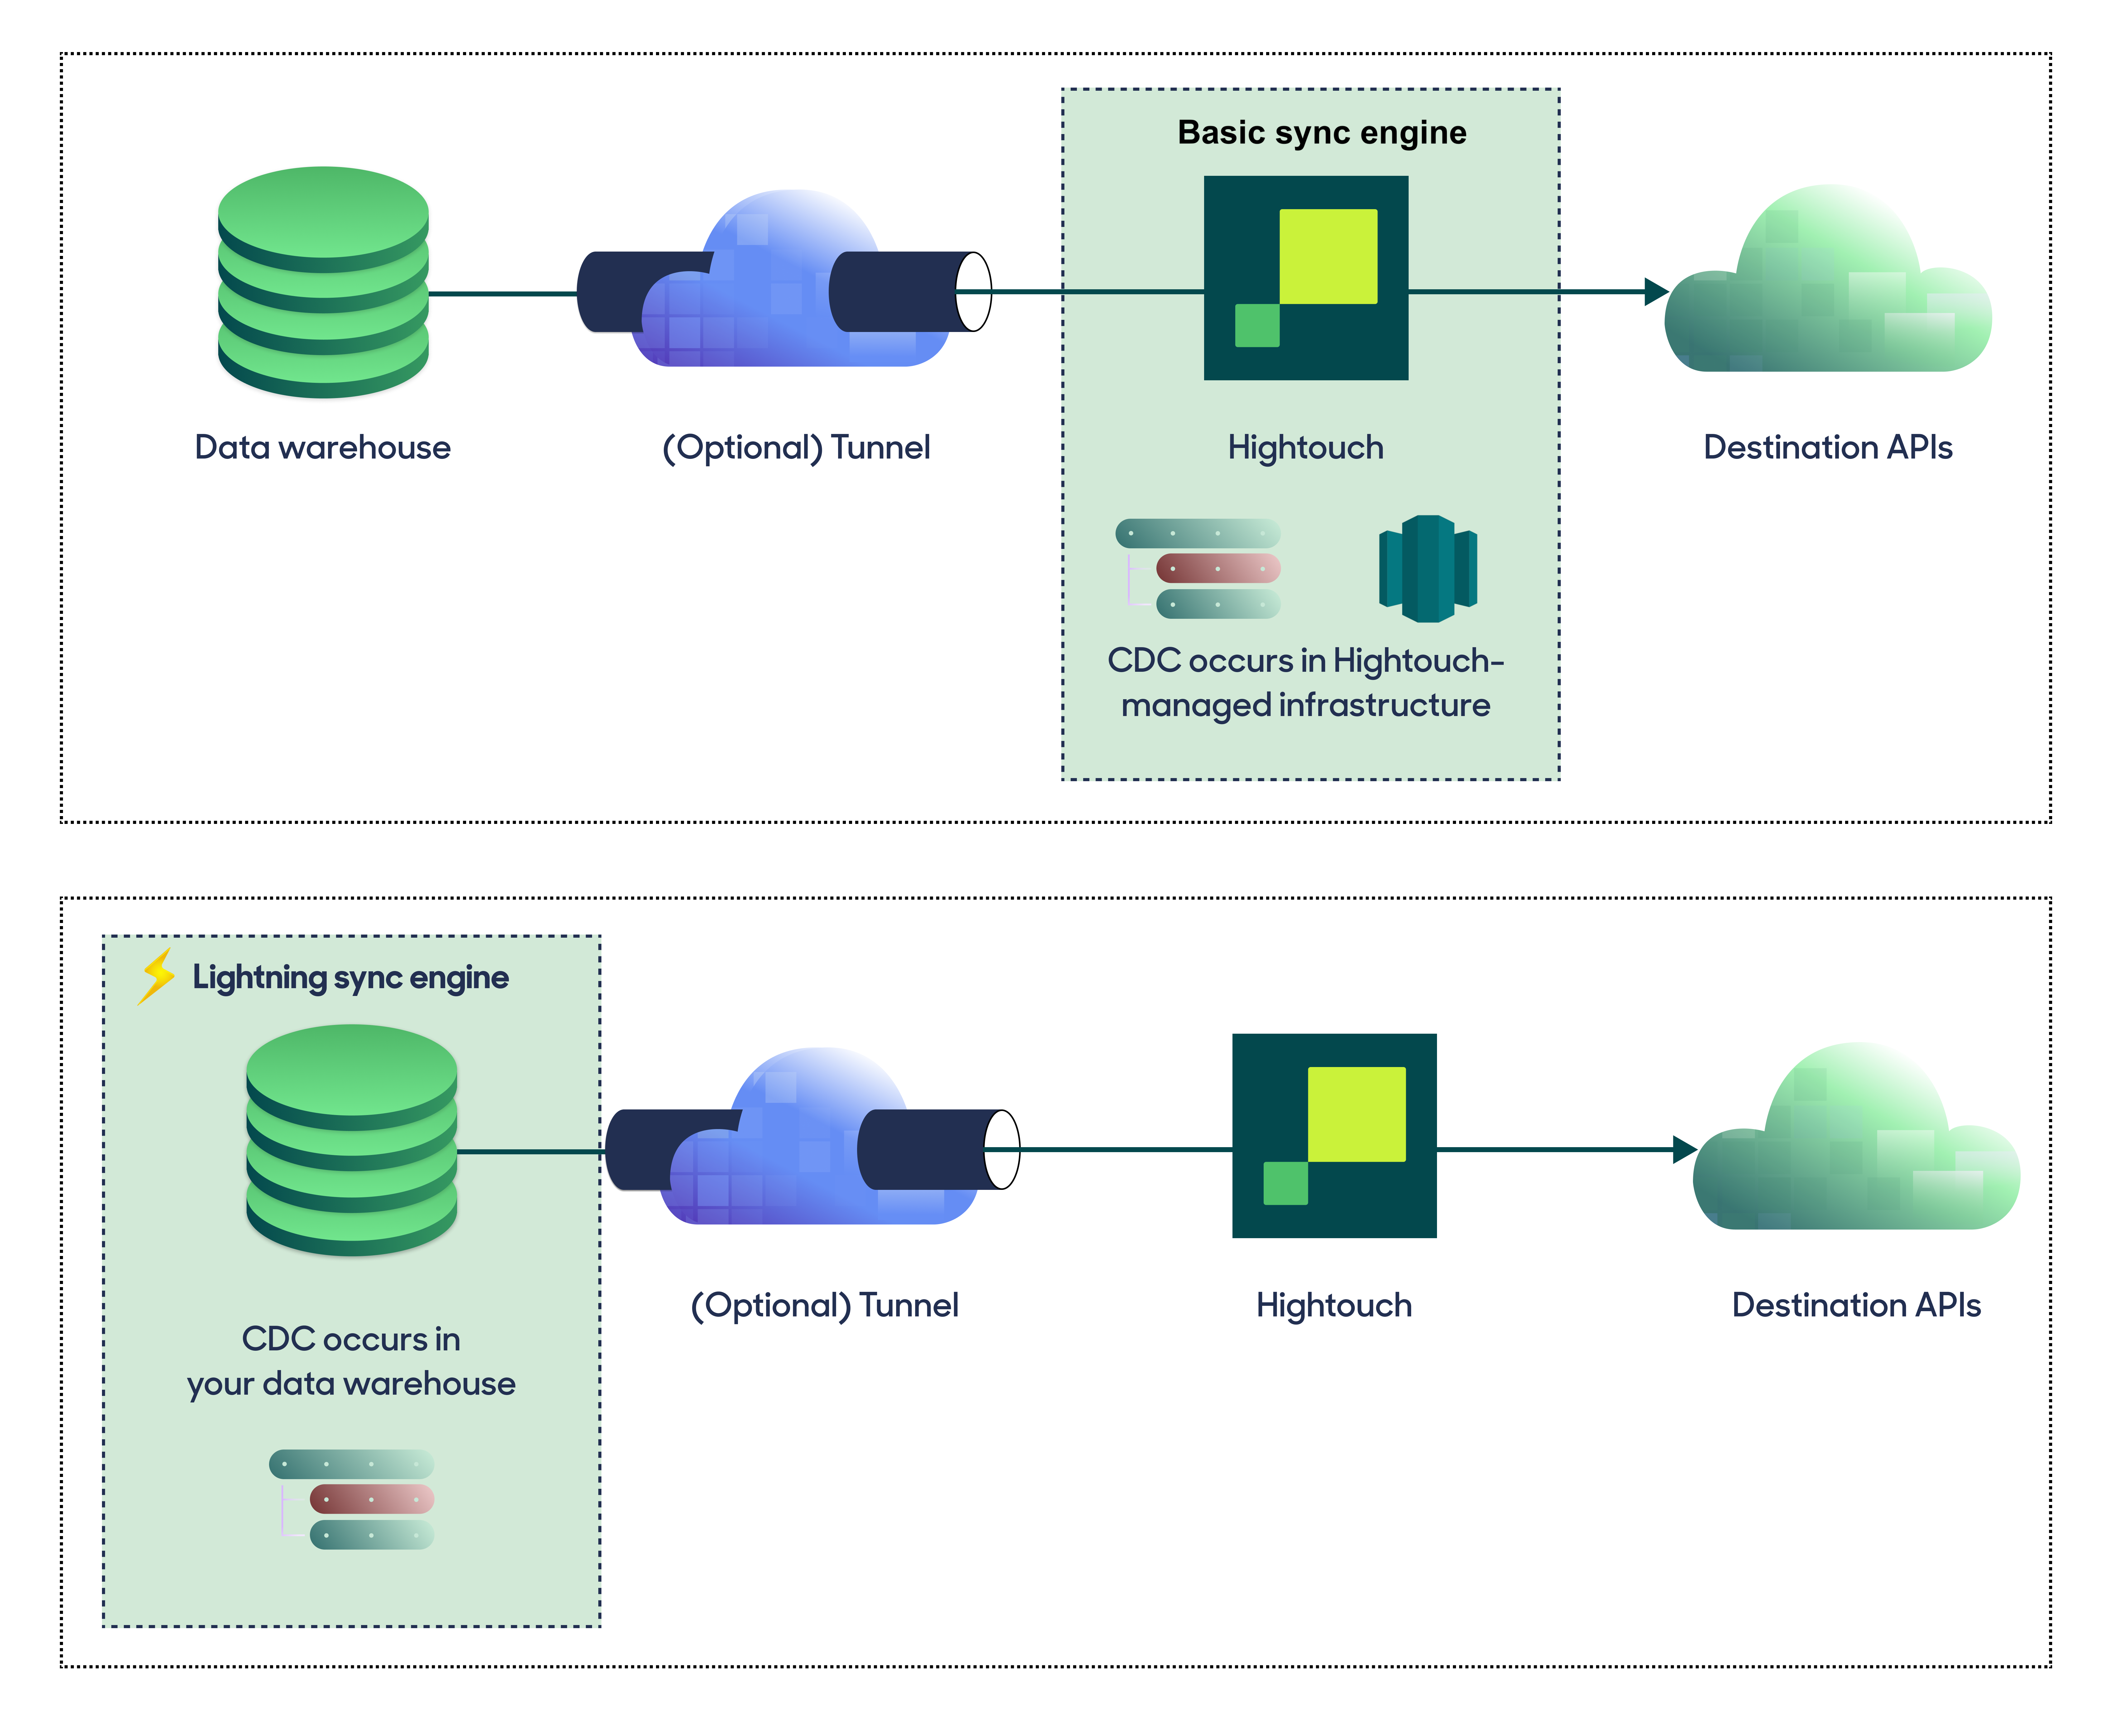
For optimal performance, Hightouch tracks incremental changes in your data model—such as added, changed, or removed rows—and only syncs those records. You can choose between two different sync engines for this work.The Basic engine requires read-only access to Synapse. Hightouch executes a query in your database, reads all query results, and then determines incremental changes using Hightouch’s infrastructure. This engine is easier to set up since it requires read—not write—access to Synapse.The Lightning engine requires read and write access to Synapse. The engine stores previously synced data in a separate schema in Synapse managed by Hightouch. In other words, the engine uses Synapse to track incremental changes to your data rather than performing these calculations in Hightouch. Therefore, these computations are completed more quickly.
Hightouch recommends using the Lightning sync engine when syncing more than 100,000 rows of data.
If you select the Basic engine, you can switch to the Lightning engine later. Once you’ve configured the Lightning engine, you can’t move back to the Basic engine without recreating Synapse as a source.To learn more, including migration steps and tips, check out the Lightning sync engine docs.
The Lightning sync engine requires granting write access to your data warehouse, which makes its setup more involved than the Basic sync engine. However, it is more performant and reliable than the Basic engine. This makes it the ideal choice to guarantee faster syncs, especially with large data models. It also supports more features, such as Warehouse Sync Logs, Match Booster, and Identity Resolution.
Criteria
Basic sync engine
Lightning sync engine
Performance
Slower
Quicker
Ideal for large data models (over 100 thousand rows)
No
Yes
Reliability
Normal
High
Resilience to sync interruptions
Normal
High
Extra features
None
Warehouse Sync Logs, Match Booster, Identity Resolution
Ease of setup
Simpler
More involved
Location of change data capture
Hightouch infrastructure
Synapse schemas managed by Hightouch
Required permissions in Synapse
Read-only
Read and write
Ability to switch
You can move to the Lightning engine at any time
You can’t move to the Basic engine once Lightning is configured
Please note that Lightning engine is only supported for Azure Synapse instances that use a dedicated SQL pool. Serverless Azure Synapse does not have the capabilities to support the Lightning engine.To set up the Lightning engine, run the following commands. Make sure to replace your_service_principal_or_user with the name of the service principal or user used to connect to your Synapse instance.The final statement grants CREATE TABLE, which is a database-scoped permission in T-SQL. Control over a schema doesn’t include it, so without this grant Hightouch can’t create the tables the Lightning engine needs.
IF NOT EXISTS (SELECT 1 FROM sys.schemas WHERE name = 'hightouch_audit')BEGIN EXEC('CREATE SCHEMA [hightouch_audit]');END;IF NOT EXISTS (SELECT 1 FROM sys.schemas WHERE name = 'hightouch_planner')BEGIN EXEC('CREATE SCHEMA [hightouch_planner]');END;GRANT CONTROL ON SCHEMA::hightouch_audit TO [your_service_principal_or_user];GRANT CONTROL ON SCHEMA::hightouch_planner TO [your_service_principal_or_user];GRANT CREATE TABLE TO [your_service_principal_or_user];
When setting up Azure Synapse as a source for the first time, Hightouch validates your credentials and access to your database. Once the test passes, click Continue to finish setup.If you see the following error message, you need to update your firewall settings in your Azure Console.
Cannot open server 'hightouch-test' request by login. Client with IP address '54.196.30.169' is not allowed to access the server. To enable access, use the Windows Azure Management Portal or run sp_set_firewall_rule on the master database to create a firewall rule for this IP address or address range. It may up take up to five minutes for this change to take effect.
Once your source configuration has passed the necessary validation, you’ve completed setting up Azure Synapse as a source. Next, you can set up models to define which data you want to pull from Azure Synapse.The Azure Synapse source supports these modeling methods: